Recommend from your own catalog, without an external engine.
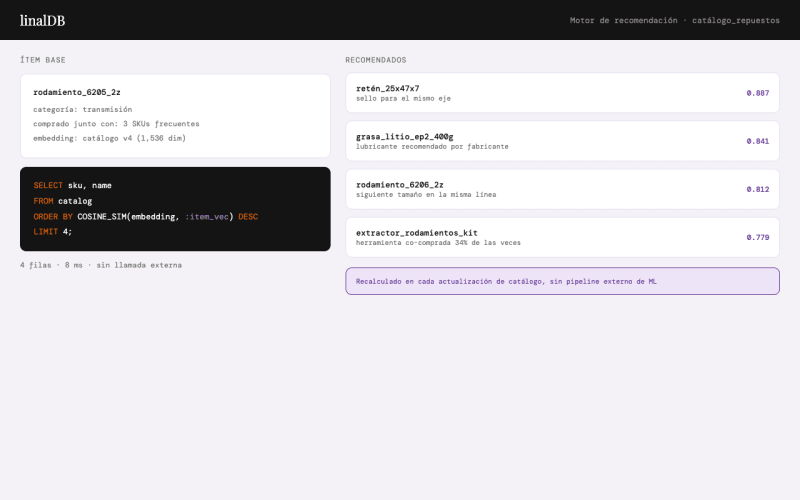
When a business wants to show a customer “you might like this” (a similar property, a similar product, a matching profile), it normally needs a recommendation engine separate from the catalog. We do it from the same database your catalog already lives in.
Let's talk about your catalogWhat changes versus building this yourself:
Technically, here's how it runs:
How we implement it
We vectorize product or profile features (text, image, attributes) as a catalog column; CREATE VECTOR INDEX + SEARCH ... QUERY <item_vector> LIMIT k for “similar to this,” and AVG_VEC per category for recommendations based on a group's centroid.
And the boundary, no detour:
What we don't solve
We don't cover large-scale collaborative recommendation (billions of interactions, Netflix-style) or ranking with continuous retraining: for large catalogs with heavy user interaction, specialized tools are still more appropriate. The sweet spot is small to medium catalogs where dedicated infrastructure isn't justified.
Frequently asked questions
Does it work for catalogs with thousands of products?
Yes, that's exactly the sweet spot: small to medium catalogs where dedicated recommendation infrastructure isn't justified.
What if we have millions of products?
At that scale a dedicated specialized tool is probably a better fit, and we'll tell you that directly during the diagnostic.
Do we need to migrate our whole catalog?
No. A vector column gets added to the table you already have, without migrating the rest.